Explore how mismatches in Kubernetes Secrets across pods can lead to performance issues and learn strategies for effective deployment verification.
Introduction to Secret Synchronization in Kubernetes
Kubernetes deployments might seem perfectly aligned at first glance, but the intricate relationship between containerized processes and their environment variables can unveil hidden discrepancies. A recent case highlighted how one of two pods was unaware of a new key in a synced Kubernetes Secret, despite both pods originating from the same image. This scenario raises the question of how such divergences occur and how we can prevent them in the future.
The Issue at Hand
During a post-deployment review, I discovered a concerning inconsistency. One of the two running pods reported a certain environment variable as 'present,' while the other failed to do so. Strangely, queries to kubectl get secret indicated both pods referenced the same Kubernetes Secret, leading to confusion. The critical factor involved the timing of Secret synchronization relative to pod initialization.
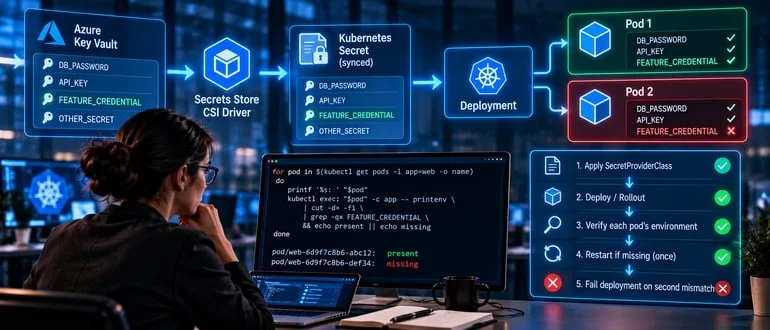
To illustrate, the deployment utilized Azure Key Vault via the Secrets Store CSI Driver. Each pod was assigned a CSI volume linked to a SecretProviderClass, which retrieved information from the vault and mirrored select values into a Kubernetes Secret that containers subsequently accessed through envFrom.
Understanding the Update Timelines
Here's the catch: The timing of updates between the Secrets Store and the pods can misalign. The CSI Driver synchronizes the Secrets only once the pod mounts the provider class. In contrast, environment variables are established upon container creation. Hence, if an update occurs after a pod is up and running, that process won’t see the change until it’s restarted.
This situation became evident when inspecting the environment variables held in the pods. Despite the native Secret reflecting the latest synchronization, each running process still held on to the data available at the moment of its creation.
The Role of Helm in Deployment
A fascinating aspect of the deployment process came into play with Helm 4.2.3. The Helm chart for this setup inadvertently placed the Deployment and the SecretProviderClass in one release while not controlling their installation order correctly. Helm processes manifests based on Kubernetes kind, sorting them accordingly. The Deployment precedes the SecretProviderClass, which can lead to a problematic timing when updates are made.
This manifested when the first pod replacement mounted the earlier version of the provider class, while the subsequent replacement synchronized with the latest key from the provider class. Such ordering issues can lead to operational challenges, as evidenced by the pod environment variable mismatch.
A Plain-Manifest Deployment Reveals Similar Challenges
A second application context further illustrated this problem. Here, the kubectl apply command applied the provider class after the rollout and health checks had already occurred. The result was that, when new keys arrived, the pods began with outdated environment settings despite the desired key being present in the native Secret. Ultimately, only pod restarts corrected the mismatch.
Adjusting the application flow to apply the provider-class before rollout ensured that existing pods maintained their current environment settings while new ones received the latest configuration.
Establishing a Deployment Verification System
To mitigate these issues, I introduced a verification step post-rollout that checks each pod for the expected key names derived from the SecretProviderClass. The goal was to ensure that every running process had the correct environment variables. If a pod missed a key, the strategy called for a one-time restart of the Deployment to rectify the situation. Should the key remain missing after the second instance, the deployment would be deemed a failure.
Such deployment gates provide a crucial layer of validation. However, they are not foolproof; if kubectl exec encounters an unreadable pod, it logs a warning but continues the process, potentially overlooking a problematic pod.
Implications for Health Checks
The findings also revealed shortcomings in the original health check mechanism, which did not engage with the integration requiring the new key. This oversight allowed the health endpoint to return a '200 OK' response, masking underlying issues. The health metrics indicated the system operated effectively, while essential configurations remained unmet. To combat this, emphasized checks must ensure that all running processes are thoroughly assessed with respect to their environment variables.
Conclusion and Best Practices
To summarize, discrepancies among pods in Kubernetes deployments can arise from poorly timed Secret synchronization and insufficient verification processes. It’s not just about ensuring that Secrets exist; it’s about confirming that every running instance aligns with the intended configuration. Thus, teams should prioritize applying the SecretProviderClass before rollout, verifying expected variable names across pods, and employing rigorous post-deployment checks to uphold service integrity.
Discussion
Sign in to join the discussion.